On this page
Choose how to split documents
Open Pipeline → Chunking and select one chunker for the space.
Through the API, replace chunk in the full pipeline configuration with
one of the JSON objects below. Use GET /api/v1/pipeline/catalog for
defaults and bounds. To apply the change and rebuild existing chunks, see
Inspect and maintain a corpus.
fixed for a token budget and overlap.
structural to retain sections, clauses, code or tables.
semantic to split prose by embedding distance.
hierarchical to match a short passage and return wider context.
late to embed passages in document context.
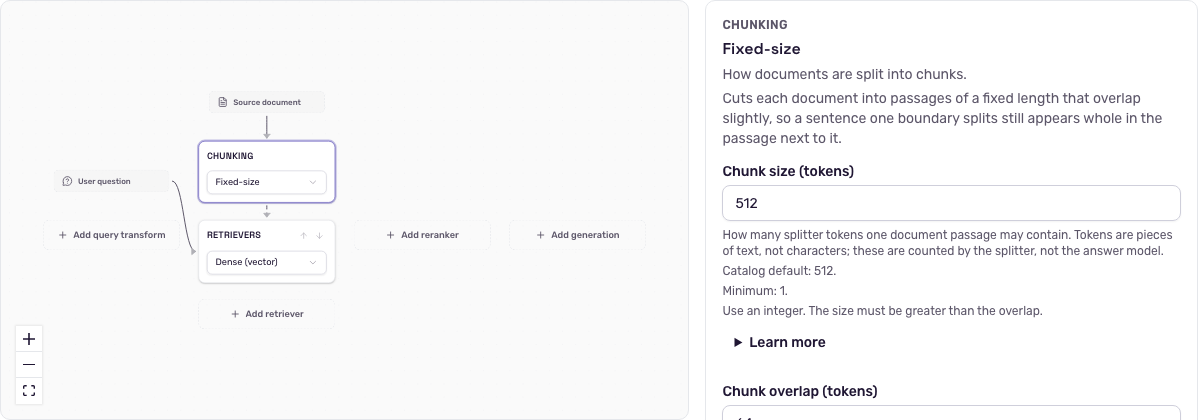
Select the node on the canvas to edit the token budget in the panel.
Fixed token budget (fixed)
Set chunk_size to the passage budget and chunk_overlap to the
shared token count. Defaults are 512 and 64 tokens, respectively. Keep
overlap below the budget. Both use the splitter’s tokeniser.
First passage
Submit the request. Attach the itinerary.
Second passage
Attach the itinerary. Wait for approval.
separator defaults to one space and paragraph_separator to three
newlines. Set secondary_chunking_regex to an empty string to skip
the fallback split at clause boundaries.
{"node":"fixed","params":{"chunk_size":384,"chunk_overlap":48}}
Preserve source structure (structural)
Set chunk_size and chunk_overlap in splitter tokens. The defaults
are 512 and 64. Overlap must be smaller than the budget, which applies to
both the source passage and the text with context.
The chunker keeps source ranges, section labels and page information when available. It subdivides oversized blocks and falls back to plain-text splitting if the structure is uncertain. Use the document title or section path for search context. Generated summaries and passage explanations are unsupported.
{"node":"structural","params":{"chunk_size":512,"chunk_overlap":48,"context_section_path":true}}
Split at topic changes (semantic)
Set breakpoint_percentile to the distance percentile that triggers a
split within a document. The default is 95 and the range is 1–100.
buffer_size includes adjacent sentences on each side when embedding a
sentence, with a default and minimum of 1. The space’s embedding model
does this work at indexing time. Passage lengths vary.
{"node":"semantic","params":{"breakpoint_percentile":90,"buffer_size":1}}
Match small passages and retain wider context (hierarchical)
Set chunk_sizes from coarse to fine in splitter tokens. The default is
[512, 128]. chunk_overlap defaults to 16, applies at every level,
and must be smaller than the smallest budget. Preflight warns if successive
budgets are equal or increase.
Parent context
Requests must include the itinerary. Approval arrives by email.
Indexed passage 1
Requests must include the itinerary.
Indexed passage 2
Approval arrives by email.
Search matches indexed child passages. The API can return surrounding
context as parent_text when a hit has a parent.
{"node":"hierarchical","params":{"chunk_sizes":[640,160],"chunk_overlap":24}}
Embed passages with surrounding context (late)
Use dense retrieval with a supported local mean-pooling model such as
nomic-ai/modernbert-embed-base where available. Preflight rejects remote
models and incompatible pooling, including CLS-based BAAI/bge-m3 from
the quickstart.
Set chunk_tokens and chunk_overlap_tokens in the model’s tokens.
Defaults are 512 and 64. Keep overlap below the window size. The model
reads long documents in overlapping passes and ContextBase pools token
states for each passage. Queries use the standard embedding path. The
text context settings below are unavailable in this mode.
{"node":"late","params":{"chunk_tokens":512,"chunk_overlap_tokens":64}}
Add searchable context
Inspect embedding_text in the chunk detail to verify the text sent for
embedding. Search still returns the original passage. Context options are
off by default.
context_document_titleprefixes the document name.context_section_pathprefixes the enclosing headings. For the fixed, semantic and hierarchical paths this uses Markdown headings outside fenced code. The structural path also uses its derived outline.context_in_lexicalincludes the same context in supported lexical and learned-sparse indexes.context_document_summarycalls an LLM once per document when no saved summary can be reused. Defaults are 8192 input characters and 160 output tokens. Thesummary_*options set the instruction, model, API base and temperature. A failed or empty summary can leave the document indexed without a summary.context_fragment_explanationcalls an LLM per passage using text from its section. Defaults are 12000 input characters and 256 output tokens. Usefragment_*for the instruction and model overrides. Matching source and settings can reuse cached explanations. A failed call aborts the cut.
Generated context needs a reachable LLM and may incur provider charges. After changing context settings, rebuild the index and rerun the same queries to compare results.
Measure the stored fragments
After indexing, open Pipeline → What a fragment holds or call
GET /api/v1/spaces/{space_id}/chunks/sizes with read access. Each cut
reports the fragment count, configured budget when present, and median and
mean sizes. Compare token counts in the same unit and check how many
fragments were measured when counts are partial. Late chunking reports the
budget and measured characters.
Fragment size report